
Double Llama 3.3 Speed with Hugging Face TGI
The open-access large language model (LLM) ecosystem continues to grow rapidly. In July 2024, Meta unveiled Llama 3.1, an impressive 405-billion-parameter model that pushed the boundaries of LLM performance. Just five months later, in December 2024, Meta released Llama 3.3, a compact version with only 70 billion parameters.
Despite being almost six times smaller, Llama 3.3 matches the performance of its larger predecessor. It even outperforms GPT-4o on several tasks, while being up to 50 times cheaper and 10 times faster than OpenAI’s model.
What makes Llama 3.3 truly exciting is its fine-tuning capability. You can train it on your own data to make it even more effective for your specific needs.
This blog focuses on creating a competitive edge with AI. If you want to ensure your competitors can’t easily replicate your product, you need to train your own AI models. Llama 3.3 is an excellent option for applications involving text or conversations.
But once your model is fine-tuned, the next challenge arises: how do you deploy it? How can you ensure your LLM delivers high performance, integrates with standard tools, and works securely within your organization?
Huggingface Text Generation Inference
The Huggingface ecosystem offers much more than just repositories for models and datasets. With Text Generation Inference (TGI), you can deploy your fine-tuned LLM for fast, efficient, and secure inference.
TGI is optimized for enterprise use, allowing you to:
- Deploy models with a simple launcher.
- Achieve production-grade performance with features like distributed tracing (OpenTelemetry) and Prometheus metrics.
- Use Tensor Parallelism for faster inference across multiple GPUs.
- Stream tokens in real-time with Server-Sent Events (SSE).
- Apply quantization with tools like bitsandbytes and GPT-Q to optimize performance.
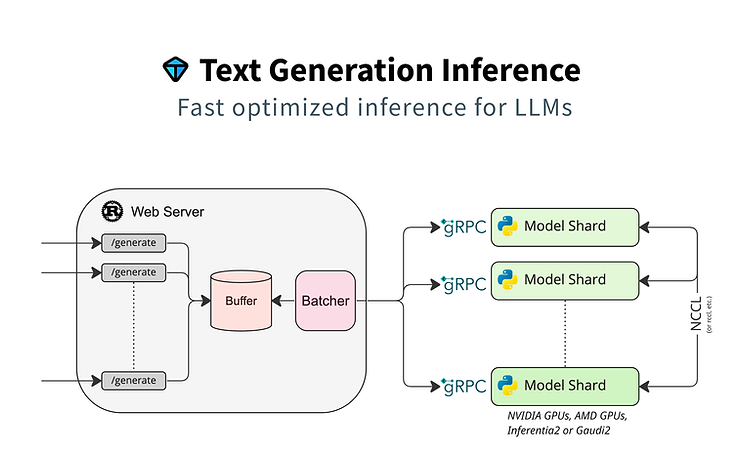
TGI also powers HuggingChat, a free AI chatbot where you can try models like Llama 3.3.
TGI is written in Rust, making it highly optimized for inference tasks. It supports out-of-the-box connectors for tools like LangChain, ensuring seamless integration with standard libraries. Whether you’re looking for speed, scalability, or simplicity, TGI delivers.
In this blog, we will demonstrate Llama 3.3 inference using standard Transformers, then deploy it with TGI and compare its generation speed.
Deploying with Hyperstack
For this demonstration, we will use Hyperstack, a GPU cloud provider offering NVIDIA H100 GPUs at a competitive rate of $1.90 per hour.
Step 1: Select Your GPU
To run Llama 3.3 effectively, we need at least two NVIDIA H100 GPUs with 80 GB of GPU memory each. While it is technically possible to run Llama 3.3 on a single H100 GPU, the model weights would need to be split between the GPU and CPU. This setup drastically increases response times, often exceeding 10 minutes per request, which is impractical for most applications.
Step 2: Choose the Operating System
Next, select an operating system that includes Docker. Docker is essential for running TGI smoothly.
Step 3: Enable Remote Access
When configuring your virtual machine (VM), enable both SSH Access for secure command-line management and a Public IP Address to allow remote connections during the experiment.
Step 4: Deploy Your VM
Once your configuration is complete, click Deploy. Within seconds, your VM will be ready to use. To enable remote access for the Jupyter Notebook, configure an ingress rule for the desired port. In this demonstration, we’ll use port 10000.
Llama 3.3 Inference with Transformers
To begin, we will test the inference speed of Llama 3.3 using the standard Transformers library. Later, we’ll deploy the same model with TGI to compare performance.
Step 1: Load the Llama 3.3 Model
Hyperstack provides 750 GB of ephemeral storage per GPU, giving us 1.5 TB of total storage with two H100 GPUs. Keep in mind that Llama 3.3 is a gated model. You’ll need to apply for access on Huggingface or directly with Meta.
pip3 install packaging huggingface_hub[cli]
huggingface-cli login --token <YOUR_HUGGINGFACE_TOKEN>
Next, load the model:
from transformers import AutoTokenizer, AutoModelForCausalLM
import torch

model_name = 'meta-llama/Llama-3.3-70B-Instruct'

tokenizer = AutoTokenizer.from_pretrained(
    model_name, trust_remote_code=True, cache_dir="/ephemeral/"
)

model = AutoModelForCausalLM.from_pretrained(
    model_name, trust_remote_code=True, torch_dtype=torch.bfloat16,
    device_map="auto", cache_dir="/ephemeral/"
)
Step 2: Load the Dataset
For this demonstration, we’ll use the Alpaca dataset:
from datasets import load_dataset

train_set = load_dataset("yahma/alpaca-cleaned", split="train")
With the Transformers library, you’ll need to format the input according to Llama’s prompt structure:
def create_prompt_formats(sample):
    result = f"""<|start_header_id|>system<|end_header_id|>

You are a helpful assistant.<|eot_id|><|start_header_id|>user<|end_header_id|>

{sample['instruction']}<|eot_id|><|start_header_id|>assistant<|end_header_id|>
"""
    sample["prompt"] = result
    return sample

train_set_processed = train_set.map(create_prompt_formats)
terminators = [tokenizer.eos_token_id]Step 3: Measure Inference Speed
To test inference speed, we’ll run the model on the first 10 inputs from the Alpaca dataset:
import time
from statistics import mean

transformers_processing_time = []

for i in range(10):
    start_time = time.time()
    data_point = train_set_processed[i]
    inputs = tokenizer(data_point['prompt'], return_tensors="pt",
                       add_special_tokens=False).to('cuda')
    outputs = model.generate(
        input_ids=inputs['input_ids'],
        attention_mask=inputs['attention_mask'],
        max_new_tokens=30000,
        pad_token_id=18610,
        eos_token_id=terminators
    )
    processing_time = time.time() - start_time
    transformers_processing_time.append(processing_time)

print(mean(transformers_processing_time))
# Output: ~30.37 seconds
On average, it takes about 30 seconds per example using this approach.
Step 4: Test with Transformers Pipeline
The Transformers pipeline simplifies batch processing. Let’s see if it improves performance:
from transformers import pipeline

pipe = pipeline("text-generation", model=model, tokenizer=tokenizer)

generation_args = {
    "max_new_tokens": 30000,
    "return_full_text": True,
    "temperature": 0.0,
    "do_sample": False,
}

transformers_pipeline_processing_time = []

for i in range(10):
    start_time = time.time()
    data_point = train_set_processed[i]
    output = pipe(data_point['prompt'], **generation_args)
    processing_time = time.time() - start_time
    transformers_pipeline_processing_time.append(processing_time)

print(mean(transformers_pipeline_processing_time))
# Output: ~28.31 seconds
Using the pipeline reduces the average processing time slightly, but it still takes around 28–30 seconds per example.
Llama 3.3 Inference with TGI
Now, let’s test Llama 3.3 with TGI. Before starting, ensure that your Python kernels are stopped, and your GPU memory is fully cleared.
Step 1: Run the TGI Docker Container
model=meta-llama/Llama-3.3-70B-Instruct
volume=/ephemeral/data

docker run --gpus all --shm-size=1g \
  -e HUGGING_FACE_HUB_TOKEN=<YOUR_HUGGINGFACE_TOKEN> \
  -v $volume:/data \
  -d -p 8080:80 \
  ghcr.io/huggingface/text-generation-inference:3.0.1 \
  --model-id $model --num-shard 2
When you run this command, Docker will pull the TGI container, download Llama 3.3 weights, and start the necessary shards. Once the model is operational, you’ll see the following log message:
INFO text_generation_router::server: router/src/server.rs:2402: ConnectedStep 2: Connect to TGI
from langchain.prompts import SystemMessagePromptTemplate, \
    HumanMessagePromptTemplate, ChatPromptTemplate
from langchain_huggingface import HuggingFaceEndpoint
from langchain_experimental.chat_models.llm_wrapper import ChatWrapper
import time
from statistics import mean
Step 3: Set Up Prompts
class Llama3Chat(ChatWrapper):
    @property
    def _llm_type(self) -> str:
        return "meta-llama/Llama-3.3-70B-Instruct"
    sys_beg: str = "<|begin_of_text|><|start_header_id|>system<|end_header_id|>\n\n"
    sys_end: str = "<|eot_id|>"
    ai_n_beg: str = ""
    ai_n_end: str = "<|eot_id|>"
    usr_n_beg: str = "<|start_header_id|>user<|end_header_id|>\n\n"
    usr_n_end: str = "<|eot_id|><|start_header_id|>assistant<|end_header_id|>\n\n"
    usr_0_beg: str = "<|start_header_id|>user<|end_header_id|>\n\n"
    usr_0_end: str = "<|eot_id|><|start_header_id|>assistant<|end_header_id|>\n\n"
def get_response():
system_template = "You are a helpful assistant."
user_template = "{message}"
messages = [
SystemMessagePromptTemplate.from_template(system_template),
HumanMessagePromptTemplate.from_template(user_template)
]
return ChatPromptTemplate(messages=messages)Step 4: Connect LangChain to TGI
llm = Llama3Chat(
    llm=HuggingFaceEndpoint(
        endpoint_url="http://127.0.0.1:8080",
        task="text-generation",
        max_new_tokens=10000,
        huggingfacehub_api_token="<YOUR_HUGGINGFACE_TOKEN>"
    )
)
Step 5: Test Inference Speed
tgi_processing_time = []

for i in range(10):
    start_time = time.time()
    data_point = train_set[i]
    response = llm.invoke({'message': data_point['instruction']}).strip()
    processing_time = time.time() - start_time
    tgi_processing_time.append(processing_time)

print(mean(tgi_processing_time))
# Output: ~14.21 seconds
On average, TGI processes each input in 14.2 seconds\u2014more than twice as fast as the 28\u201330 seconds it took with the Transformers library.
TGI provides a significant performance boost, cutting inference times by more than half. Beyond Llama 3.3, TGI supports models like Mistral, Mixtral, Gemma, Qwen, Falcon, and more, all with the same impressive efficiency. With TGI, you can deploy powerful models on your own infrastructure, ensuring that no data leaves your security perimeter.
Owning your custom LLM could enhance data security and compliance and enable an AI competitive advantage for your product. Check our other posts:
- What the network effect is and how AI enables it
- How to build an AI competitive advantage
- What culture helps you build the right AI products
- What to avoid in your AI strategy and execution
Ready to Deploy LLMs on Your Own Infrastructure?
From model selection to inference optimization, let's build a secure and performant AI deployment pipeline for your product.